Does disabling Claude Code's tool search actually save you tokens?
7 min read
On this page
Setting ENABLE_TOOL_SEARCH=false does not save you tokens - it costs more, on every turn, for as long as the session runs. The default already withholds every tool's full schema until Claude actually searches for it; forcing the flag off just pins all of those schemas back into context permanently. The only genuinely good reasons to reach for it are a tool catalog small enough that deferral never pays for itself, or a platform that has already made the choice for you before you ever set an environment variable.
ENABLE_TOOL_SEARCH=false loads every registered tool's full definition into every turn instead of a name-only summary plus an on-demand lookup. Claude Code's own docs say upfront loading is typically faster below roughly 10 tools - not cheaper. Several platforms and org settings already force one behavior or the other regardless of what you set.What does ENABLE_TOOL_SEARCH=false actually change
By default, tool search withholds every deferrable tool's full definition from context. Claude sees a short name-and-description summary instead, and searches your catalog only when a task needs a capability it doesn't already have loaded. Up to five matching tools load in full at a time and stay available for the rest of the conversation - until compaction trims older messages, at which point Claude searches again if it needs them.
ENABLE_TOOL_SEARCH=false turns that off. Every registered tool that would otherwise be deferrable - MCP tools from remote or custom SDK servers, plus the on-demand built-ins - loads its complete schema into every single turn, whether Claude touches it or not. Nothing about the core built-ins changes either way: Bash, Read, and Edit always load upfront and were never part of the deferral pool.
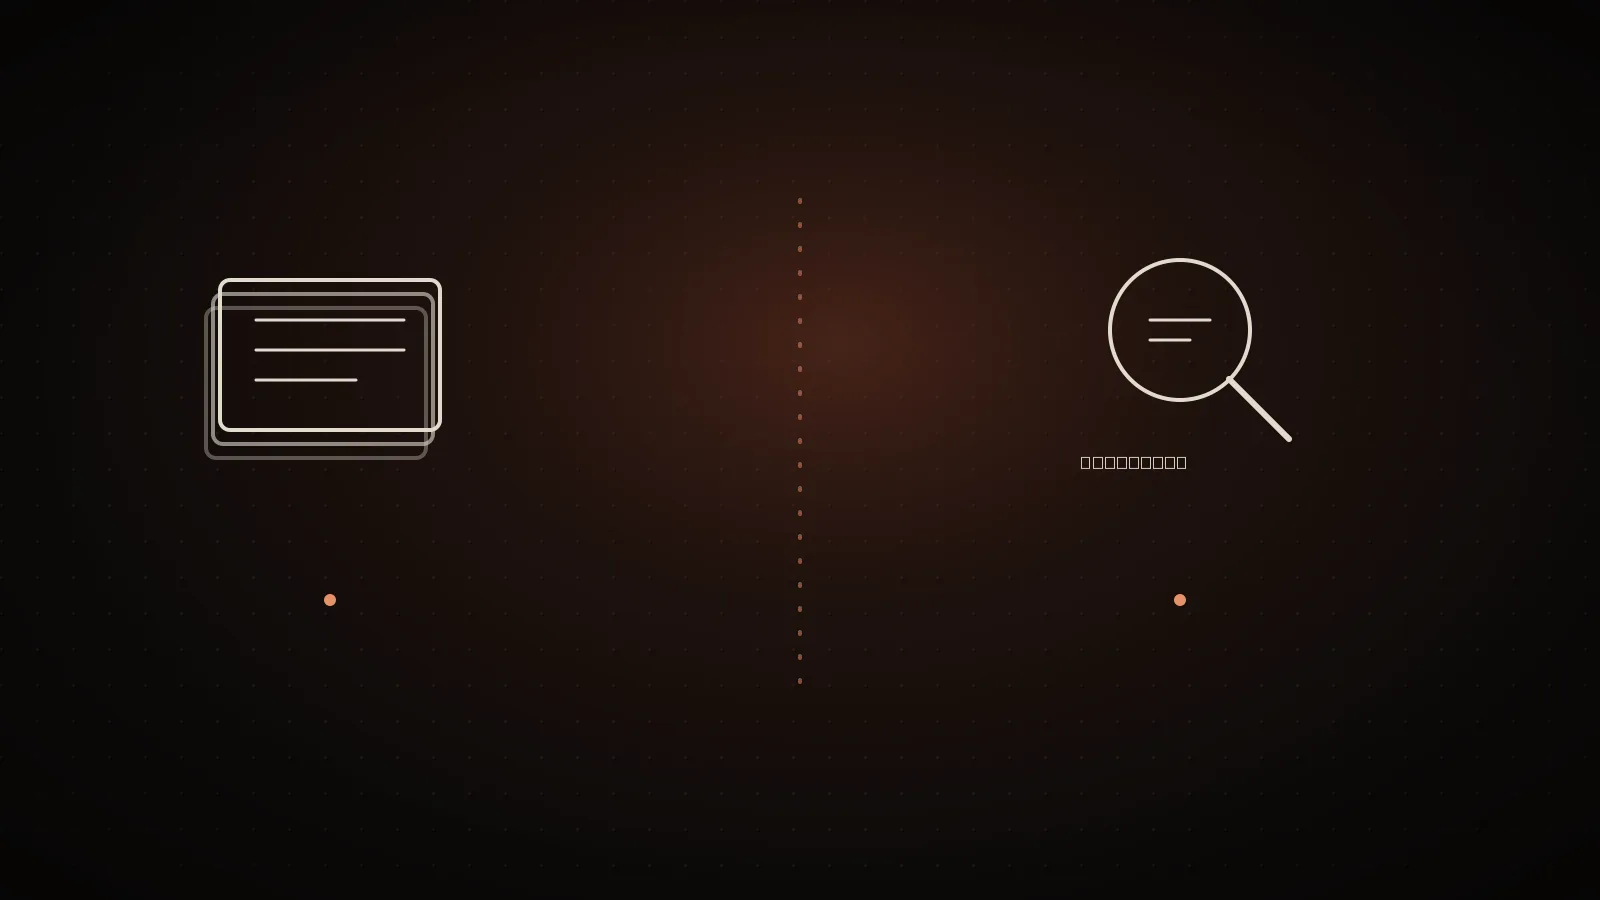
Every registered tool's full schema loads into context, every turn, whether Claude calls it or not. No summary phase, no search step.
Claude sees a name-only summary. It searches on first need, loads up to five matches, and keeps them until compaction evicts them.
The left path pays its full cost every turn. The right path pays one extra round-trip the first time, then stays small.
Does disabling it save tokens, or cost you more
It costs more, and the gap widens with your tool count. Anthropic's own engineering post on the underlying mechanism measured a five-tool-server setup at roughly 55K tokens of full definitions dropping to about 8.7K tokens once deferred - an 85% reduction, Anthropic's own benchmark, not this project's. Turning false off recovers exactly that spread: full definitions, every turn, for as long as the session lasts, whether or not any of it ever gets called.
There's a second cost that isn't about tokens at all: Claude Code's docs note that tool-selection accuracy degrades once more than 30-50 tool definitions sit loaded in context simultaneously. Forcing everything upfront on a large catalog doesn't just spend more tokens, it also makes Claude more likely to reach for the wrong tool. Anthropic's benchmark reported accuracy climbing from 49% to 74% on Opus 4 and from 79.5% to 88.1% on Opus 4.5 once deferral was in place - the opposite direction from what disabling search buys you.
The one place the math gets close is a catalog small enough that the deferred summary plus one search round-trip costs about the same as just loading everything - the "fewer than ~10 tools" line Claude Code's own docs draw. Even there, what you're trading is a small amount of first-use latency, not tokens. Below that line, disabling search doesn't cost you much either way; it just stops being worth touching.
When Claude Code is already loading everything upfront for you
Four of the cases below are decided before ENABLE_TOOL_SEARCH is ever read, by your model generation, your platform, or an org policy - setting the variable does nothing in any of them.
Four of six are decided by your model, platform, or org policy - not by ENABLE_TOOL_SEARCH. Check these before assuming the flag does anything.
The GitHub feature request asking Anthropic to let native tools be disabled outright (#1380) is closed as of August 2025, four comments, no reopen since - the friction it described predates tool search shipping as the actual answer to "too many tool definitions eating context."
What tool search actually did in this session, counted
This guide was built inside a real Claude Code session connected to an MCP server carrying dozens of tools. Here's what tool search actually did with that catalog, counted directly from this run's own transcript rather than modeled:
tools arrived name-only
18 built-ins + 61 MCP tools, before any search
search calls, whole build
each one narrowly scoped to what the step needed
ever got a full schema
19% of the 79 - the rest never loaded
Measured directly from this run's own tool-call transcript, not modeled. The other 64 tools sat deferred for the entire build and cost nothing beyond their name and a one-line description.
That's the deferral mechanism working exactly as documented: the vast majority of a configured catalog never needs its full schema at all in a given session, and forcing all 79 upfront on every turn - which is precisely what ENABLE_TOOL_SEARCH=false would have done here - would have meant carrying 64 unused schemas the whole way through for nothing.
The other lever: disabling servers you never call at all
Tool search and server disabling change different things. Tool search decides when a schema loads - deferred by default, forced upfront if you disable it. Removing or toggling off an MCP server decides whether it costs anything at all: an idle-but-configured server still adds its name and up to 2KB of instructions to every turn, deferred schema or not, until you actually turn it off.
The two stack. A setup with six configured servers and only two in real use pays the idle-server tax on the other four no matter what ENABLE_TOOL_SEARCH is set to, and pays the full-schema tax on top of that if search is off. The tool search savings calculator prices the deferral gap for your actual mcpServers config against a custom auto:N threshold; the MCP server cost checker prices the idle-server baseline the same servers carry regardless of tool search. Run a config through both before touching either lever.
A checklist for whether to touch ENABLE_TOOL_SEARCH at all
- Count your actual tool catalog - configured MCP tools plus on-demand built-ins. Under roughly 10, the default barely matters either way; there's nothing worth optimizing here.
- Check whether your platform already decides it for you. Azure-hosted Microsoft Foundry, a pre-4.5-generation model, an older Google Cloud Agent Platform generation, or
CLAUDE_CODE_DISABLE_EXPERIMENTAL_BETASall override the flag - setting it does nothing in any of those cases. - If you have a large catalog and want a middle ground instead of fully off, tune
auto:Nrather thanfalse- it keeps deferral for everything except the servers small enough to fit comfortably upfront. - If you suspect tool search itself is missing a tool that genuinely exists, set
ENABLE_TOOL_SEARCH=falsetemporarily as a diagnostic - confirm the tool works when loaded directly, then file it as a search-quality bug rather than living with search off permanently.
When leaving the default alone is correct
For most Claude Code setups today, doing nothing is the right call. Tool search's default already gets you the deferral for free, no configuration required, and disabling it needs one of the specific cases above to actually be true - not just a general feeling that "fewer settings would be simpler." If you're not sure how many tools your own setup is carrying, count your configured MCP servers' tool lists directly rather than guessing from memory.
FAQ
- Does turning off tool search save tokens? No. It removes deferral, so every registered tool's full schema loads into every turn instead of a name-only summary - the opposite of a saving.
- Is tool search on by default in Claude Code? Yes, for Claude Opus 4.5, Sonnet 4.5, Haiku 4.5, and later models, with documented exceptions for certain platforms and older model generations.
- What's the difference between
auto:Nandfalse?auto:Nkeeps deferral for tool definitions until they cross N% of the context window, then loads them upfront - a threshold.falseloads everything upfront unconditionally, no threshold. - Can
ENABLE_TOOL_SEARCHoverrideCLAUDE_CODE_DISABLE_EXPERIMENTAL_BETAS? No. If that variable is set, tool search stays off regardless of whatENABLE_TOOL_SEARCHsays. - If I only have a few tools, should I disable tool search? Not for tokens - under roughly 10 tools the cost difference is small either way. The only thing you'd be trading is a small amount of first-use search latency.
- Is the old GitHub request to disable native tools still open? No. #1380 closed in August 2025; tool search shipped as the actual fix for the context-budget problem it was describing.
None of this requires guessing at your own tool count by hand. The free scan reads your real Claude Code session history and setup directly and reports exactly what's configured, deferred, or costing you either way, and the context window calculator puts this one setting into the full budget picture.
See your own numbers
These are aggregates from real sessions. Your setup is different - run the free scan and get the breakdown for your own Claude Code history. It runs locally; nothing about your code or prompts leaves your machine.
npx usagecutRun a free scan → Made by Neo
UsageCut by ClockedCode - not affiliated with Anthropic. The figures on this page are measured on real Claude Code sessions and labeled measured or estimated where it matters.